Step 1
Play it once
The agent opens your H5 or WebGL build in the source language and explores it the way a player would, tapping through menus, shops, popups and dialogs. It records the route to every screen it finds.
Output: a map of your screens
Replayproof is an AI QA agent for H5 and WebGL games. It plays your build once, replays the same route in every target language and captures every screen it reaches. It flags localization and smoke defects, then audits each finding against its screenshot before you see it.
One screen, four languages, same route
Real captures from one run on Lanternmoor, our own test game with seeded defects (2026-11-11). Boxes are the issues the audit confirmed.
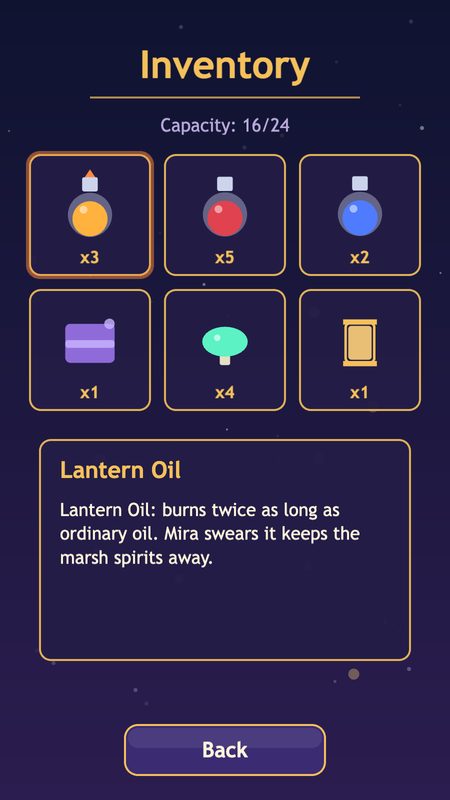
Route: Title > Menu > Inventory
Source language, no findings
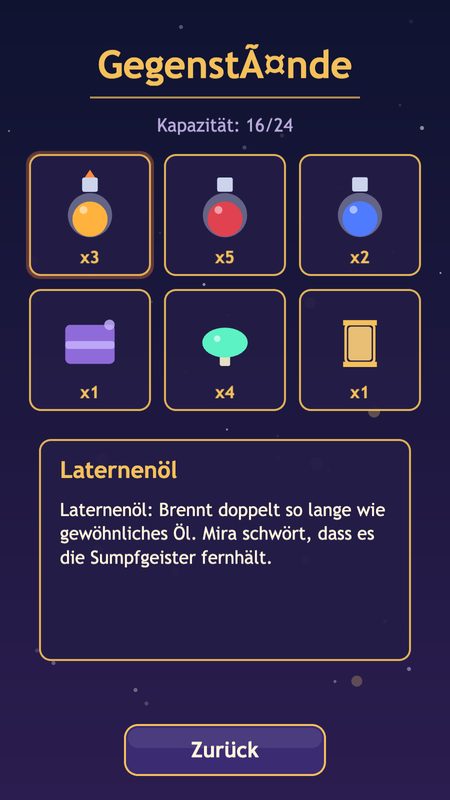
Route: Title > Menu > Inventory
1 finding
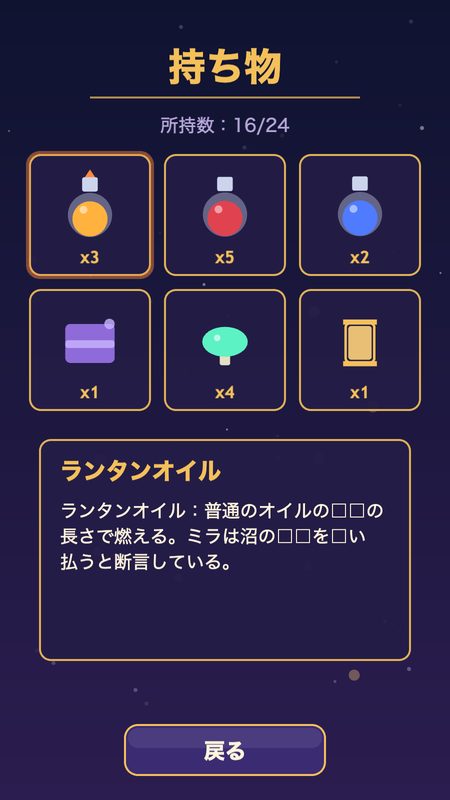
Route: Title > Menu > Inventory
1 finding
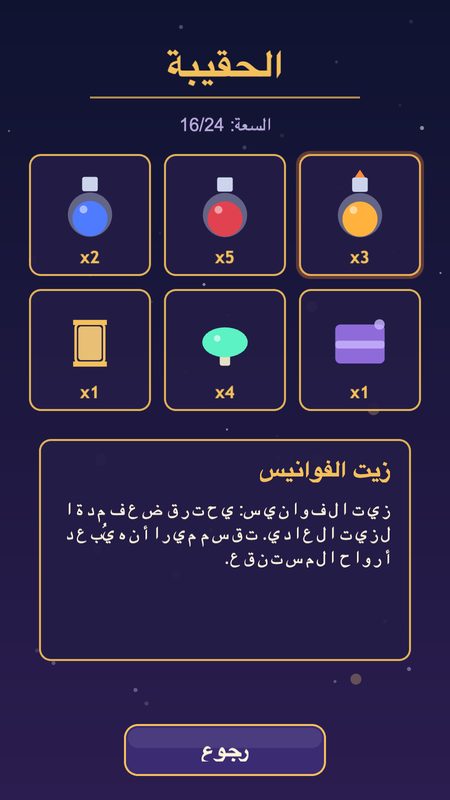
Route: Title > Menu > Inventory
1 finding
One build in, one evidence report out. The agent plays like a player and checks like a QA lead.
Step 1
The agent opens your H5 or WebGL build in the source language and explores it the way a player would, tapping through menus, shops, popups and dialogs. It records the route to every screen it finds.
Output: a map of your screens
Step 2
The same route runs again in each target language on the same build. Every screen is captured next to its source-language version, while the console and frame timing are watched for crashes and freezes.
Output: every screen, in every language
Language codes are examples. Your list decides.
Step 3
Rules check what can be checked, such as placeholders, scripts and glyphs. A vision model reviews the rest. Then a separate audit pass re-examines each candidate against its screenshot. Only confirmed findings reach the report.
Output: an evidence report
Button text overflows (DE)
Text leaves the button box in the localized frame only.
Confirmed, goes in the report
Text cut off (DE)
The full string is visible in the crop. Nothing is clipped.
Rejected, never reaches you
Two families of defects, found in the same run. Pick one from the codex to see it up close.
Text cut off at the edge of its box, or ended with an ellipsis nobody designed.
The German title is clipped to an ellipsis inside a fixed-width header.
Text that spills out of its button, panel or tile and lands on art or neighbouring elements.
A longer label leaves its button and runs over the next control.
A string left in the source language, or shown in a language other than the one selected.
One label stays English in the middle of a Japanese screen.
Raw tokens such as {0}, %s or <b> shown to players instead of the value they stand for.
A raw %s token appears where the gem count should be.
Empty boxes where the font has no character, garbled text and missing diacritics.
Empty boxes replace three characters in a reward label.
Arabic or Hebrew that is not mirrored, letters that fail to join and mixed-direction strings in the wrong order.
Arabic letters fall apart and the layout keeps its left-to-right order.
Translated text colliding with icons, counters or other text.
A long label runs under the coin counter.
Uncaught exceptions and console errors, with the message, the stack and the screen that triggered them.
An uncaught error fires on the screen where the build was switched to a new language.
The frame stops updating or the game stops answering input, and the player cannot get out.
Frames stop arriving after a tap and never resume.
A screen that renders as nothing after a transition or a language switch.
The canvas is alive but every pixel is black.
Grades on the examples are illustrative. Every finding in a real report carries its own grade.
A tool that cries wolf costs more review time than it saves. So every finding has to prove itself before it reaches you.
Each candidate is re-examined against the screenshot it came from. A separate pass confirms or rejects the specific claim and says why. Rejected candidates never reach the report.
An annotated screenshot with the defect boxed, the source-language crop beside it and the auditor's reason. Triage becomes a read, not a hunt.
The exact taps from a fresh load to the screen, so a developer can reach the bug in seconds.
Every page the agent visits is recorded, so when a freeze is hard to believe you can watch it.
Illustrative issue card
7 screens in 7 languages, run on 2026-11-11
A second run on the same build found 87% of the seeded defects with 96% of its findings real and 0 non-defects flagged. Model answers vary from run to run, so we show both.
We plant known defects and deliberate non-defects in a demo game, run the agent, and publish what it found and what it got wrong, with the defect list so you can check it.
If a build goes to several markets at once, someone has to look at every screen in every language. This is for them.
You release the same build in many markets. You want to know each market's build works before launch week, not from the first player who writes in.
You own quality across languages and vendors. The agent screens what a machine can judge, so your reviewers spend their hours on tone and culture.
Your team cannot walk every screen in every language on every build. You get a repeatable pass and a list where each issue already carries its evidence.
Run the machine pass before your linguists start. You keep the judgement work and the client relationship, and your reviewers start from a short, evidenced list. We are looking for partners to pilot this with.
No integration and nothing to install. Send a build under NDA and we scope a pilot on your own game: the languages, the screens and how we measure the result.
Tell us the build and the languages you ship. We agree the scope under NDA: which builds, which languages and which screens.
We run your build in the agreed languages and send the evidence reports. The measures are set up front: issues found against your own LQA results, false flags, hours saved.
A pilot is priced per build and per language, not per agent-hour, so the price follows the work you get.
We quote after we see your build and your language list.
First module
Play once, replay in every language, localization and smoke defects, evidence report.
Next
The same agent on every new build, to catch what changed since the last one.
Next
The same route, driven on a device instead of a browser.
We sign your NDA before we touch a build, use it only to run your pilot, and do not train models on it. Private deployment, where the agent and its checks run inside your own network, is on the roadmap.
We start with H5 and WebGL builds that load in a browser. The agent works from what is on screen, the way a player does, so it does not depend on the engine you used. Android builds are next. Native iOS, PC and console are not covered yet, and neither are WeChat mini-games. Tell us if you need one of them.
It depends on how many screens your build has and how many languages you want. We give you a turnaround when we scope the pilot, before it starts. Adding a language adds a replay of a known route, not a new exploration.
A link or package for an H5 or WebGL build, your list of target languages with the source language marked, and a way to switch language, such as a URL parameter or a stored setting. A string table and a list of known issues are optional, but they help.
No. It screens out what a machine can judge: cut-off text, leaked placeholders, missing glyphs, crashes. Your linguists keep tone, terminology and cultural fit.
Each finding comes with its screenshot and the auditor's reason, so you can reject it in seconds. Intentional things, like a brand name left in English or an HP abbreviation, go on an allowlist so they are skipped next time.